https://raw.githubusercontent.com/karpathy/makemore/988aa59/names.txt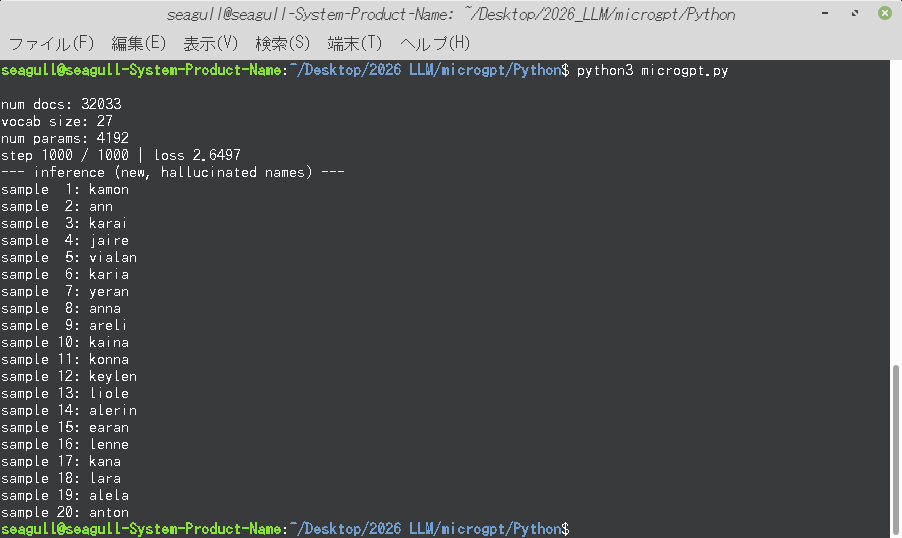
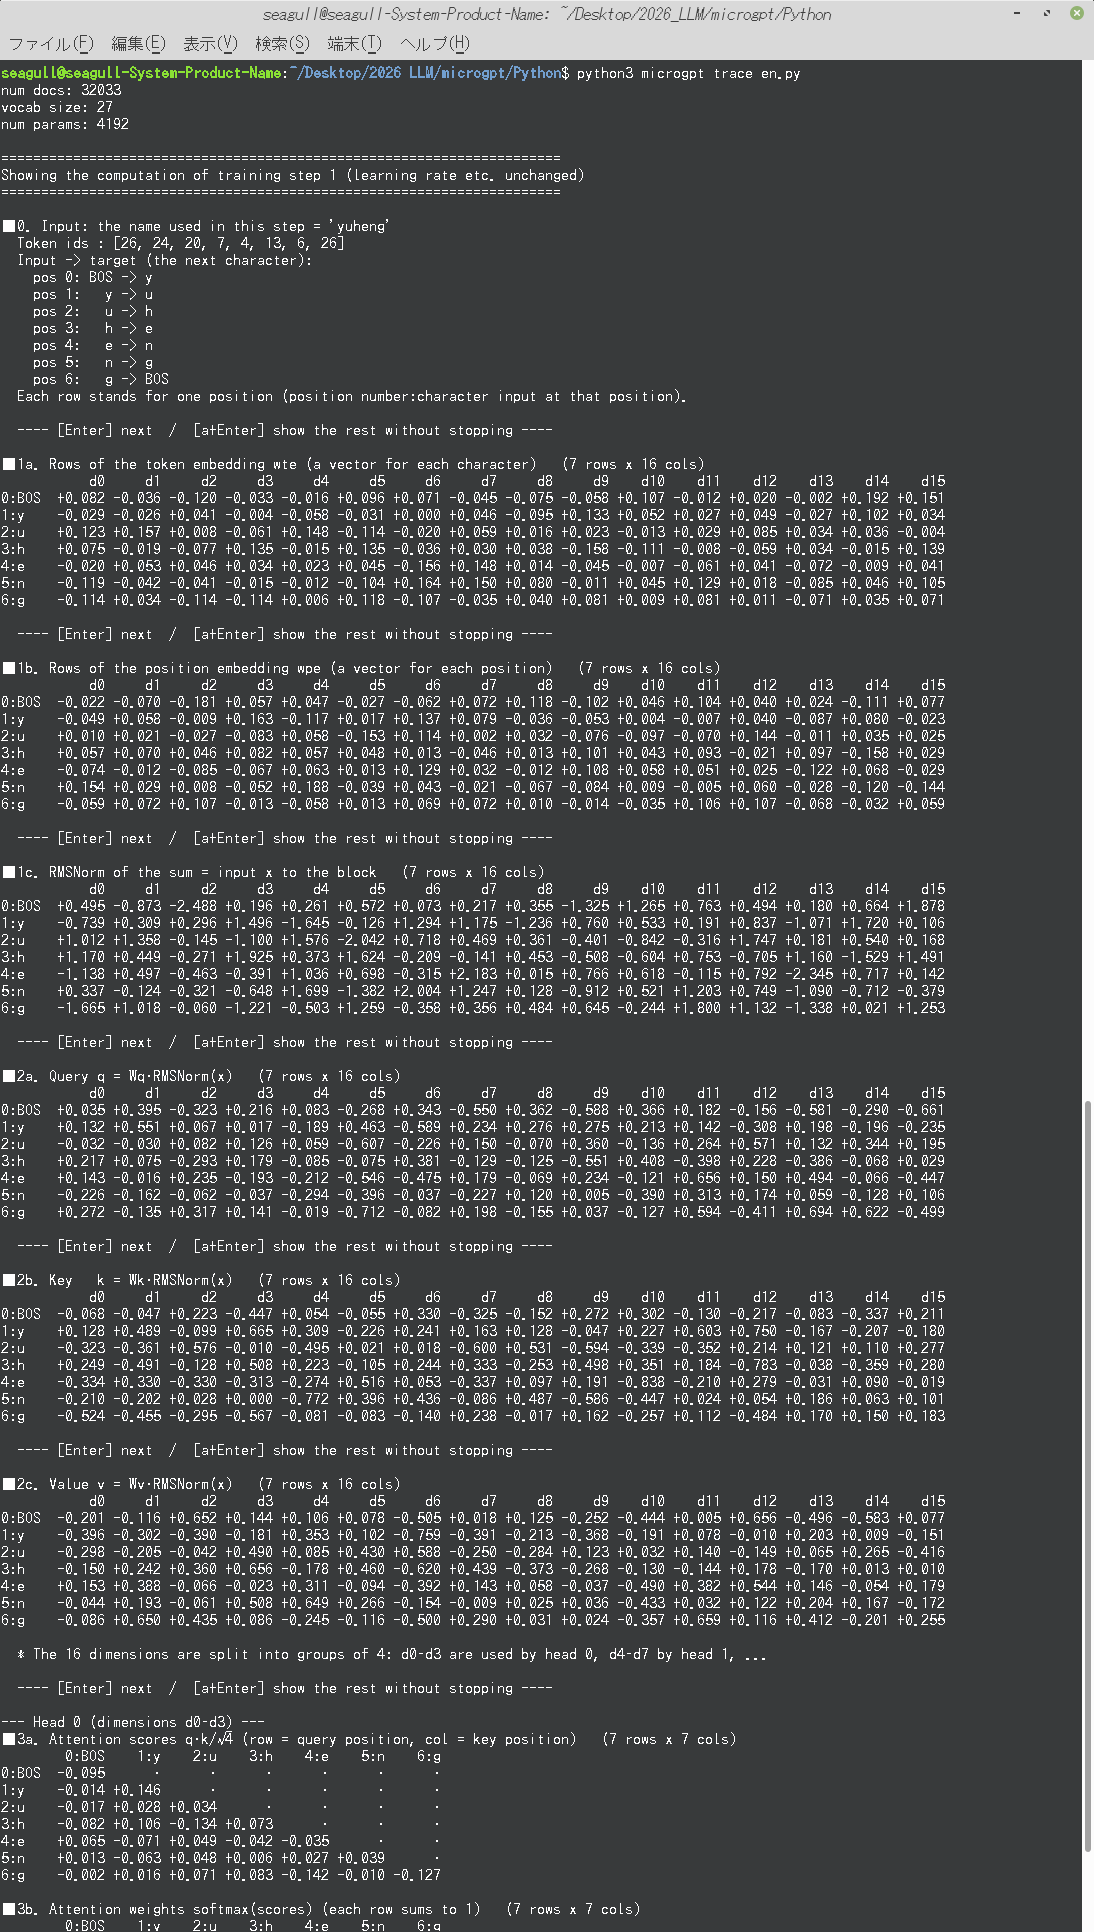
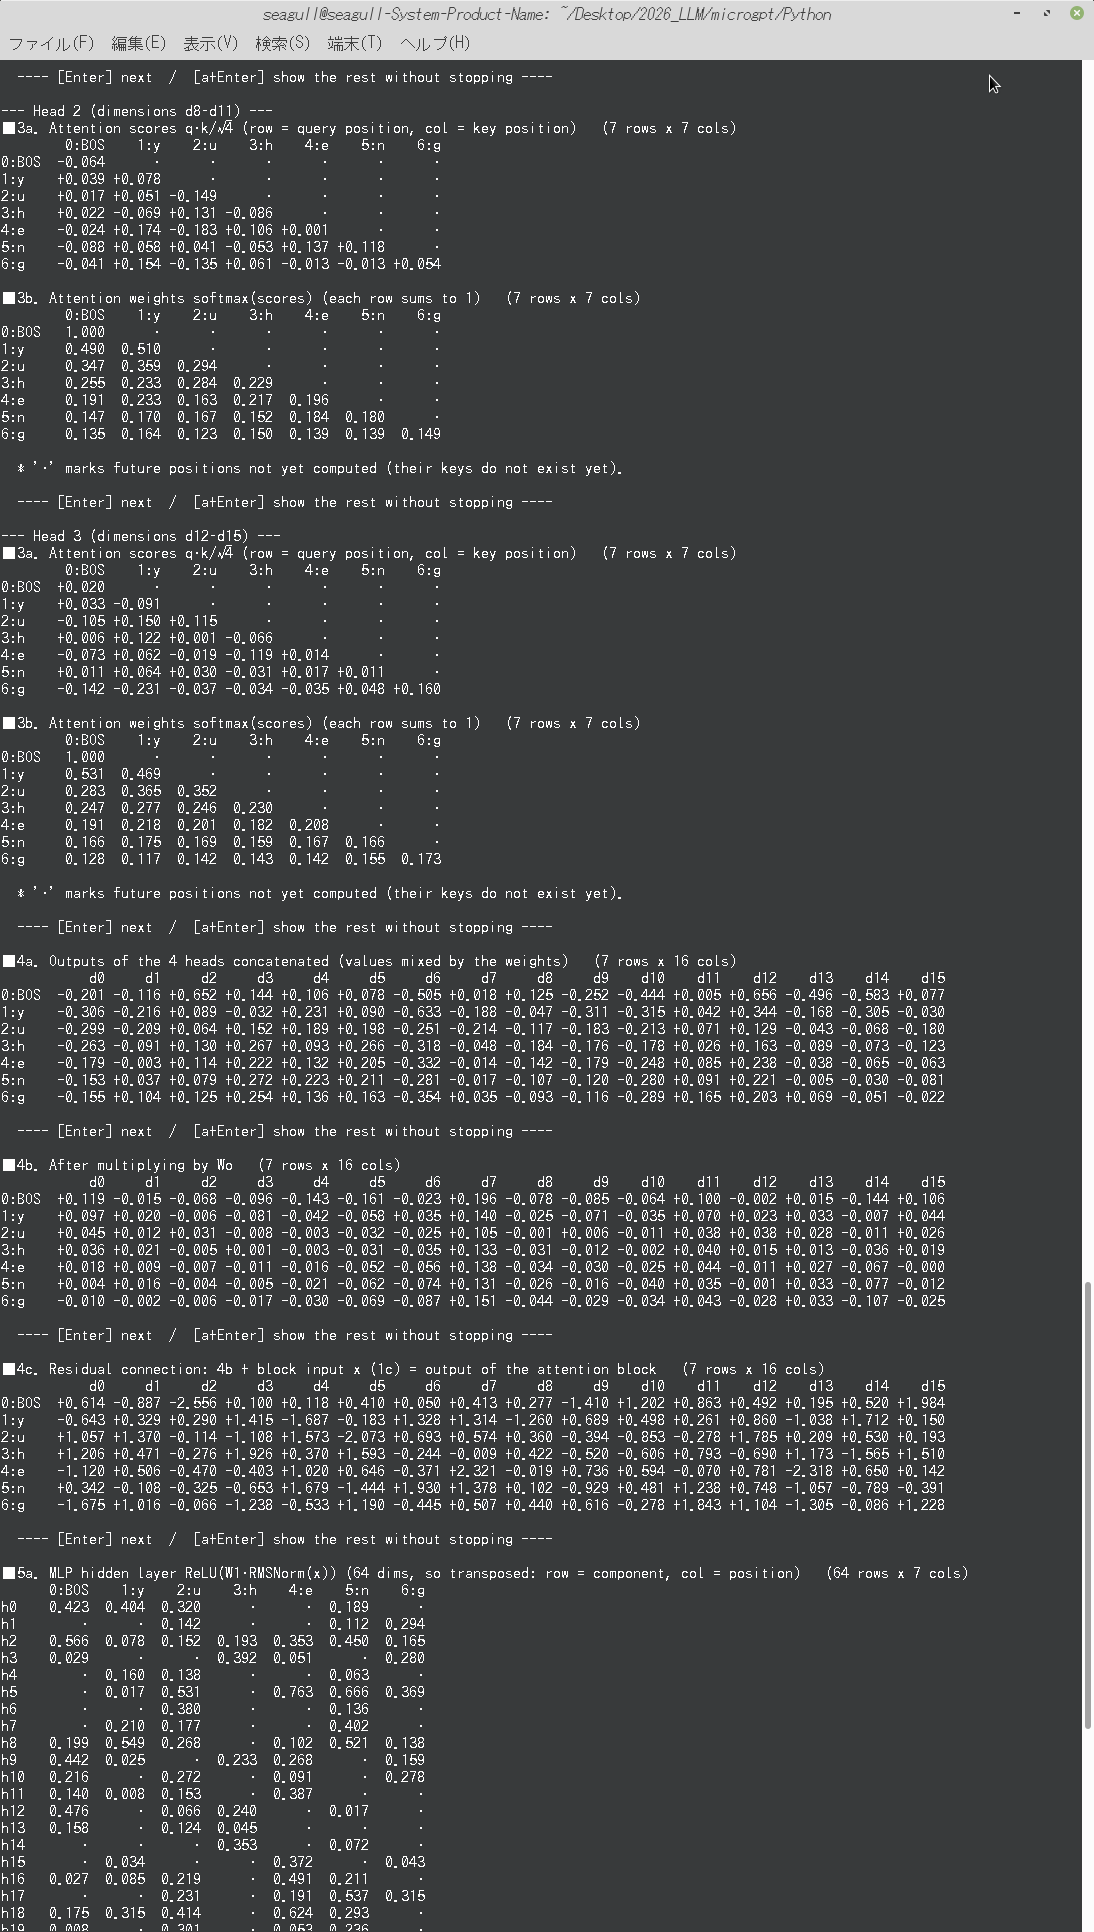
| The matrices WQ, WK, WV, WO, the MLP's W1, W2, etc. | The attention weights aij | |
|---|---|---|
| What they are | Parameters of the model | Coefficients computed from the input |
| When they are set | Set when the model is made (during training), then fixed | Computed every time, for each chat context |
| Do they change with the input? | No | Yes |
In other words,